Classification Metrics
Machine Learning: Classification
- Classification is a supervised learning approach in which the computer program learns from the data input given to it and then uses this learning to classify new observation.
- The classification is done by the computer after the learning process.
- Classification is a technique where we categorize data into a given number of classes. The main goal of a classification problem is to identify the category/class to which a new data will fall under.
- Example are face detection, email spam detection, credit card fraud detection, etc.
Confusion Matrix
- Tabular visualization of the model predictions versus the actual labels.
- Each row of the confusion matrix represents the instances in an actual class whereas each column represents the instances in a predicted class.
- Consider a binary classification problem having Covid+ and Covid- classes. The confusion matrix will look like this:
  |                   | Predicted Covid+    | Predicted Covid-    |
  |-------------------|---------------------|---------------------|
  | Actual Covid+     | True Positive (TP)  | False Negative (FN) |
  | Actual Covid-     | False Positive (FP) | True Negative (TN)  |
-
True Positive (TP): The number of observations that were correctly predicted as Covid+.
-
True Negative (TN): The number of observations that were correctly predicted as Covid-.
-
False Positive (FP): The number of observations that were incorrectly predicted as Covid+.
-
False Negative (FN): The number of observations that were incorrectly predicted as Covid-.
-
Accuracy: The ratio of correctly predicted observation to the total observations. It works well only if there are equal number of samples belonging to each class.
-
Error Rate:
Note: Accuracy is not a good metric when the classes are imbalanced. (One class has more samples than the other). In this case, even if you predict all samples as the most frequesnt class you would get a high accuracy rate, which does not make sense at all (because model is not learning anything, and is just predicting everything as the top class).
-
Precision: The ratio of correctly predicted positive observations to the total predicted positive observations.
-
Recall (Sensitivity): The ratio of correctly predicted positive observations to the all observations in actual class.
-
F1 Score: The weighted average of Precision and Recall.
-
The F1 Score is the harmonic mean of Precision and Recall and gives a better measure of the incorrectly classified cases than the Accuracy Metric.
Colab
Gram-Schmidt Process
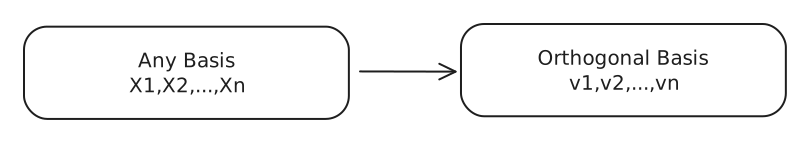
- The Gram-Schmidt process is a method for orthonormalizing a set of vectors in an inner product space.
- The Gram-Schmidt process takes a finite, linearly independent set S = {v1, v2, …, vn} for n ≥ 1 and generates an orthogonal set S’ = {u1, u2, …, un} that spans the same subspace of R^n as S.
Properties of the Gram-Schmidt Process
- for .
- span() = span().
- is orthogonal to .
- where is the projection of onto the subspace spanned by .
- is the distance from to the subspace spanned by .